Reinforcement Learning Greedy Policy
Creator: Petar Veličković (original)
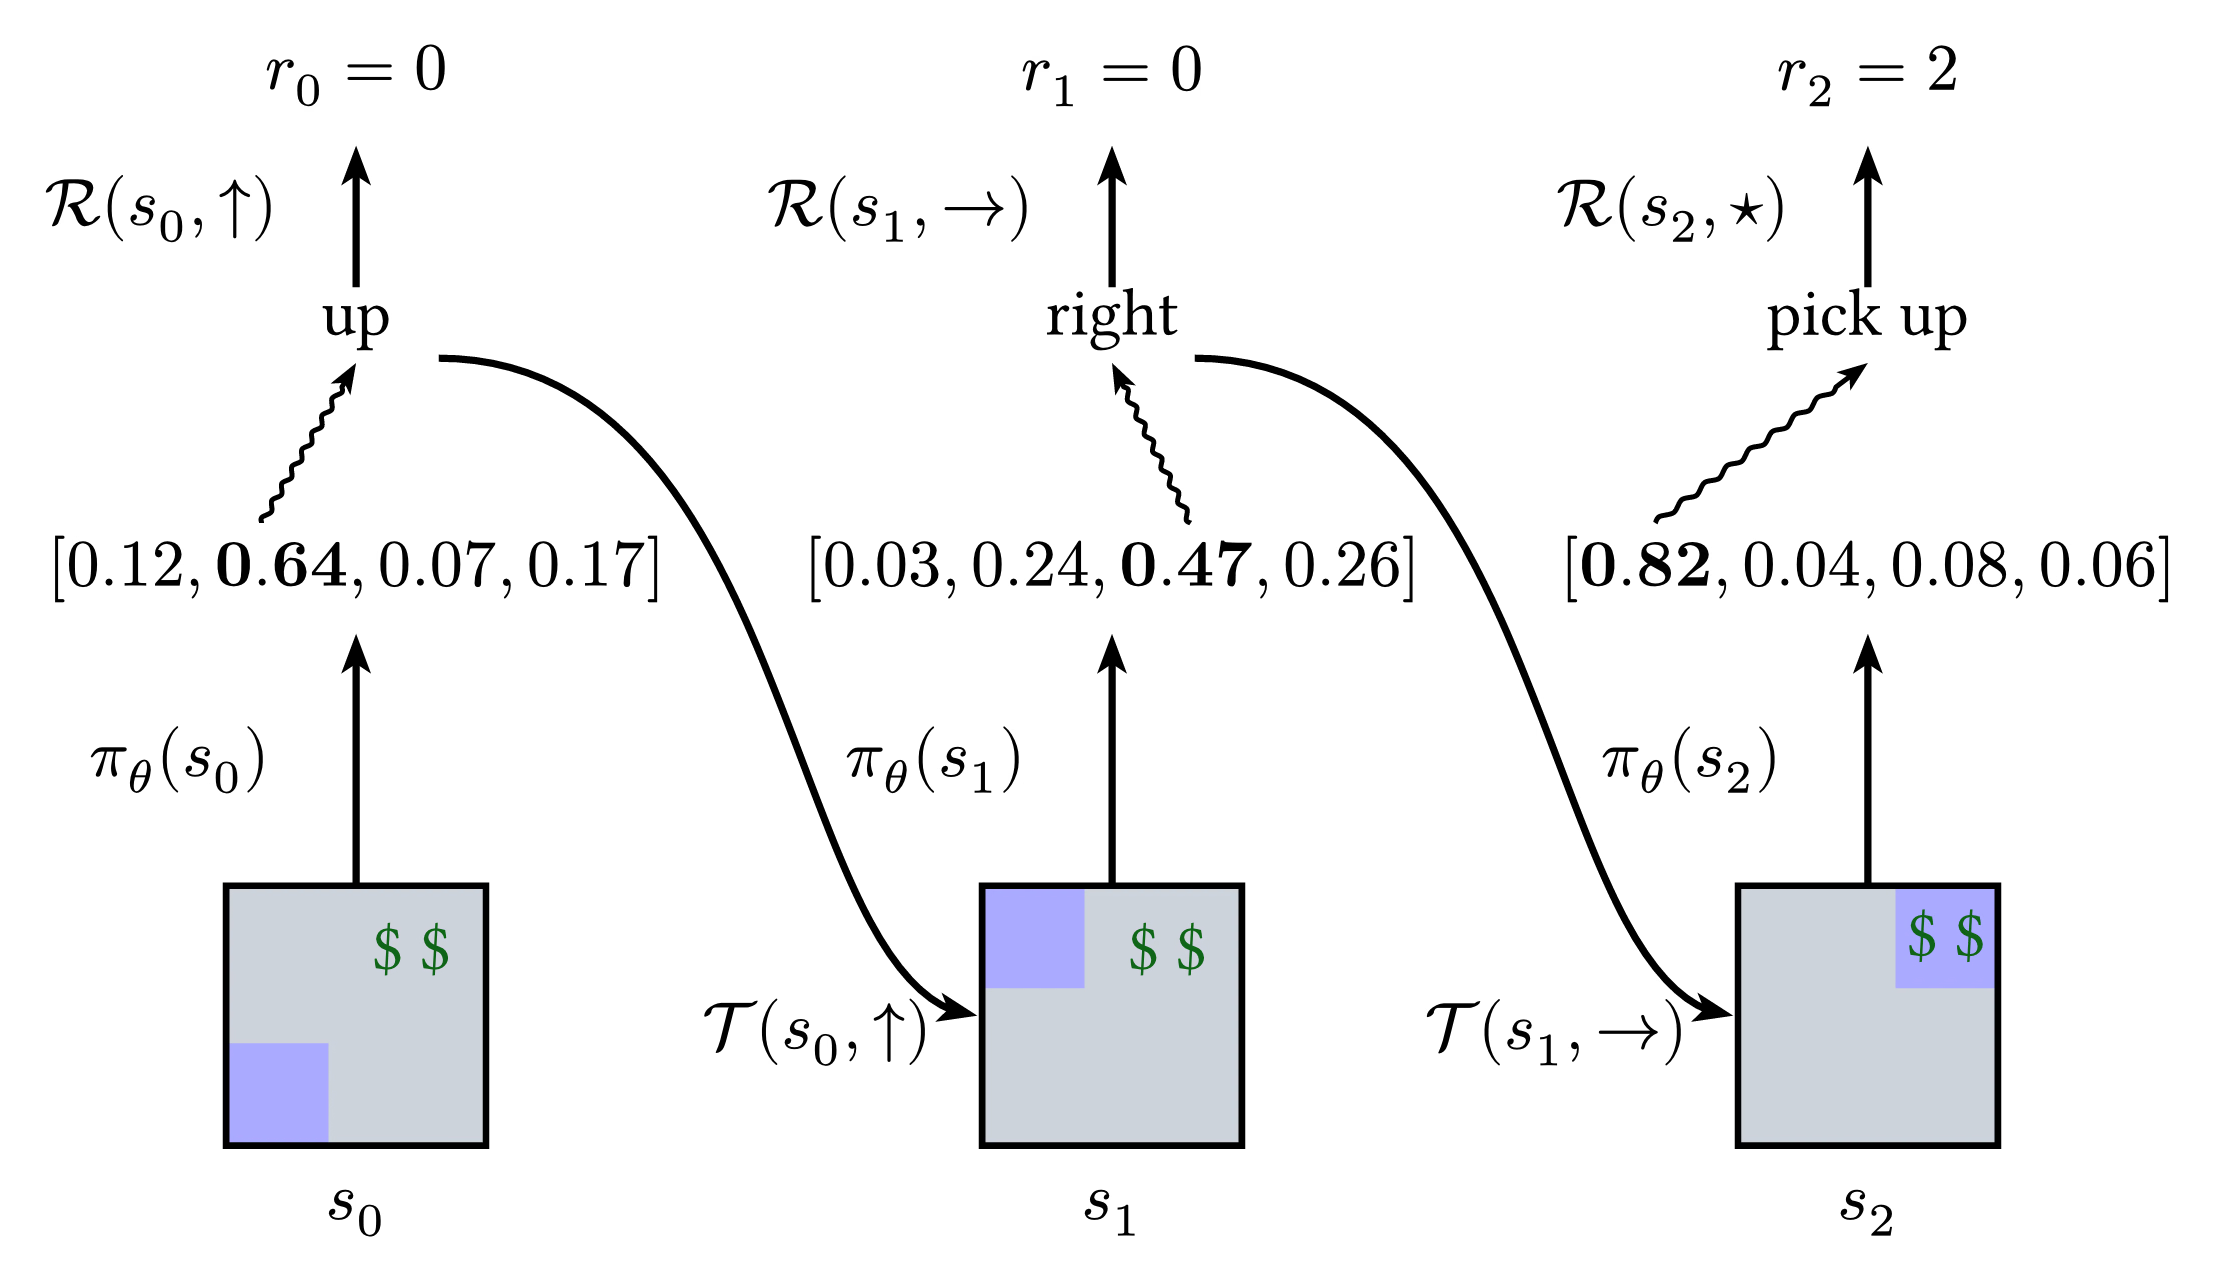
A three-step rollout of a greedy policy in a small grid world. In each state , the policy scores the available actions and the agent takes the highest-scoring one (bold), receiving reward and moving to the next state via the transition . Moving up and right earns nothing, while picking up the money (green dollar signs) at the goal earns .
Download
Code
#import "@preview/cetz:0.5.3": canvas, decorations, draw
#import draw: bezier, content, line, rect

#set page(width: auto, height: auto, margin: 8pt, fill: none)
#set text(size: 12pt)

// Darker than Typst green so the goal reward reads on the grey cells in both page themes.
#let green = rgb("#0f6418")
#canvas({
  let arrow = (mark: (end: "stealth", fill: black, scale: .55), stroke: .9pt)
  let heavy = (mark: (end: "stealth", fill: black, scale: .65), stroke: 1.3pt)
  let panel-w = 1.65
  let marker-w = .65
  let y-box = -3.9
  let state-gap = 4.8
  let west-rim(x) = (x - .03, y-box + panel-w / 2)

  // Grid-world panel (agent marker, $$ goal) with the policy output, chosen action and reward above it.
  let state(x, idx, q, action, reward, symbol, mark-pos, greedy-x, dollar-pos) = {
    let (mid, top) = (x + panel-w / 2, y-box + panel-w)
    let panel = ((x, y-box), (x + panel-w, top))
    rect(..panel, stroke: none, fill: rgb("#cdd3da"), name: "panel")
    rect(
      (rel: mark-pos, to: "panel.south-west"),
      (rel: (mark-pos.at(0) + marker-w, mark-pos.at(1) + marker-w), to: "panel.south-west"),
      fill: rgb("#aaaaff"),
      stroke: none,
    )
    rect(..panel, stroke: 1.2pt, fill: none)
    content((rel: dollar-pos, to: "panel.south-west"), text(fill: green)[\$ \$], anchor: "center")
    content((rel: (0, -.28), to: "panel.south"), $s_#idx$, anchor: "north")

    line("panel.north", (rel: (0, 1.6), to: "panel.north"), ..heavy, name: "policy")
    content((rel: (-.55, -.8), to: "policy.end"), $pi_(theta)(s_#idx)$, anchor: "east")
    content((rel: (0, .2), to: "policy.end"), q, anchor: "south", name: "scores")
    content((rel: (0, 1.8), to: "policy.end"), action, anchor: "south", name: "action")
    // squiggle from the greedy score up to the chosen action, straightening into the arrowhead
    decorations.wave(
      line(
        (rel: (0, .08), to: ((mid + greedy-x, 0), "|-", "scores.north")),
        (rel: (0, -.08), to: "action.south"),
      ),
      amplitude: .035,
      segments: 8,
      stop: 85%,
      ..arrow,
    )
    line(
      (rel: (0, 2.2), to: "policy.end"),
      (rel: (0, 3.1), to: "policy.end"),
      ..heavy,
      name: "reward",
    )
    content((rel: (-.5, .05), to: "reward.mid"), $cal(R)(s_#idx, #symbol)$, anchor: "east")
    content((rel: (0, .25), to: "reward.end"), $r_#idx = #reward$, anchor: "south")
  }

  // Policy scores with the greedy choice in bold, then marker and $$ positions in the panel
  for (idx, (q, action, reward, symbol, mark-pos, greedy-x, dollar-pos)) in (
    ($[0.12, bold(0.64), 0.07, 0.17]$, [up], 0, "↑", (0, 0), -.6, (1.18, 1.24)),
    ($[0.03, 0.24, bold(0.47), 0.26]$, [right], 0, "→", (0, panel-w - marker-w), .5, (1.18, 1.24)),
    (
      $[bold(0.82), 0.04, 0.08, 0.06]$,
      [pick up],
      2,
      "⋆",
      (panel-w - marker-w, panel-w - marker-w),
      -1.35,
      (panel-w - marker-w / 2, panel-w - marker-w / 2),
    ),
  ).enumerate() {
    state(idx * state-gap, idx, q, action, reward, symbol, mark-pos, greedy-x, dollar-pos)
  }

  for (idx, symbol) in ("↑", "→").enumerate() {
    let (x, next-x) = (idx * state-gap, (idx + 1) * state-gap)
    bezier((x + 1.35, 1.10), west-rim(next-x), (x + 3.65, 1.10), (x + 3.55, -3.0), ..heavy)
    content(
      (next-x - .25, -3.18),
      $cal(T)(s_#idx, #symbol)$,
      anchor: "east",
      fill: rgb("#cdd3da"),
      padding: 2pt,
    )
  }
})