Regular vs Bayes NN
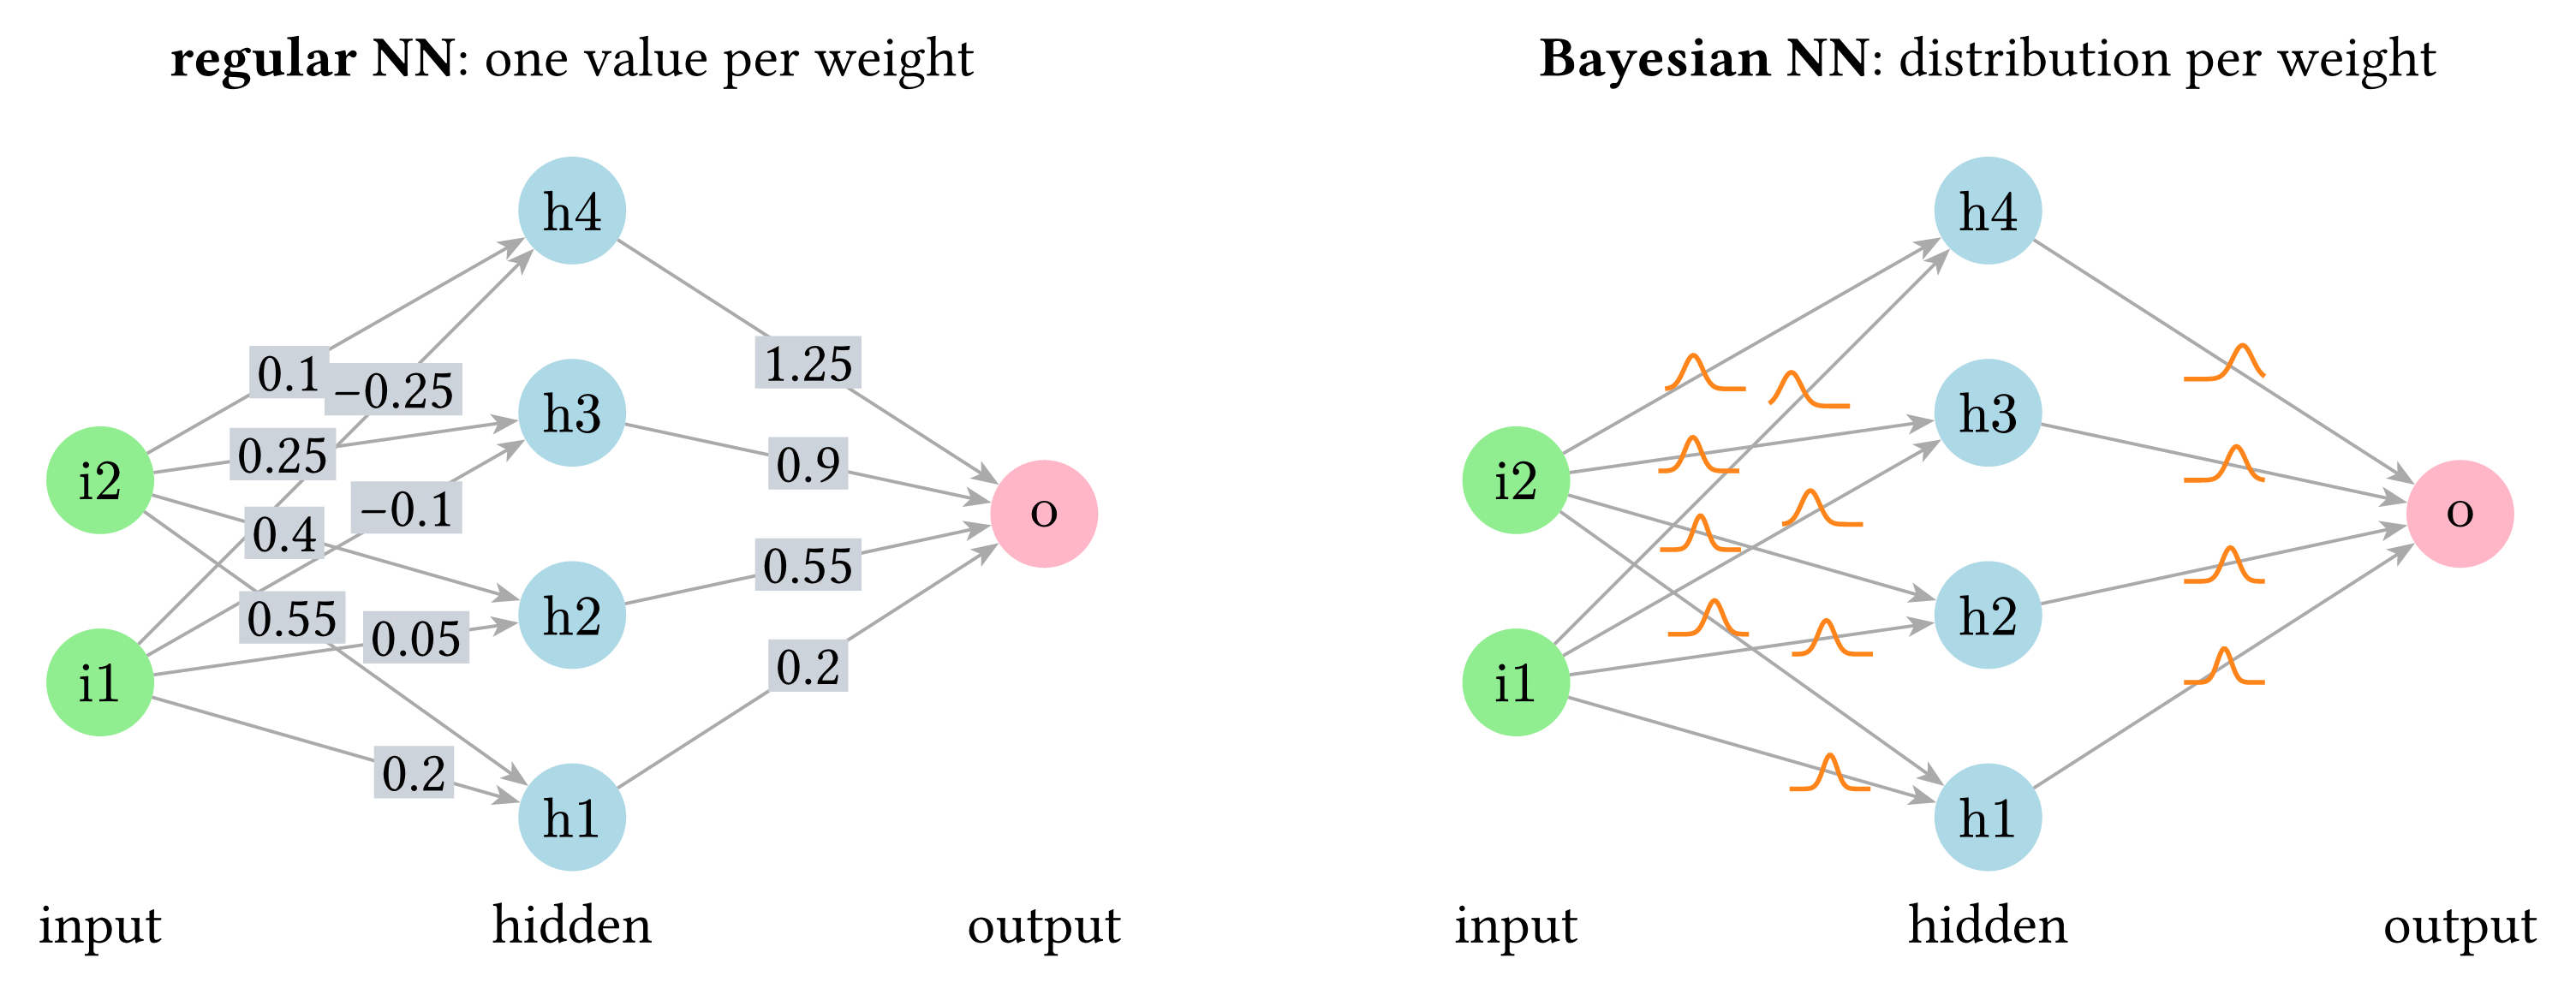
Comparison between regular neural networks and Bayesian neural networks on the same 2-4-1 architecture. The regular network (left) learns a single point-estimate value per weight, while the Bayesian network (right) learns a probability distribution over each weight, so its predictions come with uncertainty estimates.
Download
Code
#import "@preview/cetz:0.5.3": canvas, draw
#import "@preview/cetz-plot:0.1.4": plot
#import draw: circle, content, group, line, set-origin, translate

#set page(width: auto, height: auto, margin: 8pt, fill: none)
#set text(size: 12pt)

#canvas({
  let (layer-gap, node-gap) = (3.5, 1.5)
  let arrow-style = (mark: (end: "stealth", scale: 0.7), stroke: gray + 0.7pt, fill: gray)

  let neuron(pos, fill, label) = {
    circle(pos, radius: 0.4, fill: fill, stroke: none, name: label)
    content(pos, $#label$)
  }

  // Edge midpoint, slid along the edge by shift * 0.4 to keep neighboring annotations apart.
  let edge-point(start, end, shift) = ((start, 50%, end), shift * 0.4, end)

  let weight-label(pos, weight) = content(
    pos,
    [#calc.round(weight, digits: 2)],
    frame: "rect",
    fill: rgb("#cdd3da"),
    stroke: none,
    padding: 1.5pt,
  )

  // Small Gaussian glyph standing for a weight distribution; offset varies its mean and width.
  let gaussian(pos, offset) = {
    let (width, height) = (0.6, 0.25)
    let variance = 0.3 + calc.abs(offset) * 0.1
    group({
      set-origin(pos)
      translate((-width / 2, -height / 2))
      plot.plot(size: (width, height), axis-style: none, plot.add(
        style: (stroke: orange + 1pt, fill: orange.lighten(80%)),
        domain: (-1, 1),
        samples: 50,
        x => calc.exp(-5 * calc.pow(x - offset * 0.15, 2) / variance),
      ))
    })
  }

  // 2-4-1 network; decorate-ih/decorate-ho draw the per-edge annotation (weight or distribution)
  let draw-network(x0, title, decorate-ih, decorate-ho) = {
    content((x0 + layer-gap, 4 * node-gap + 0.9), title, anchor: "south")
    for (idx, layer) in ("input", "hidden", "output").enumerate() {
      content((x0 + idx * layer-gap, node-gap - 0.65), layer, anchor: "north")
    }
    let inputs = range(2).map(idx => (x0, (idx + 1) * node-gap + 1))
    let hidden = range(4).map(idx => (x0 + layer-gap, (idx + 1) * node-gap))
    let output = (x0 + 2 * layer-gap, 2.5 * node-gap)
    for (idx, pos) in inputs.enumerate() { neuron(pos, rgb("#90EE90"), "i" + str(idx + 1)) }
    for (idx, pos) in hidden.enumerate() { neuron(pos, rgb("#ADD8E6"), "h" + str(idx + 1)) }
    neuron(output, rgb("#FFB6C6"), "o")

    for (in-idx, start) in inputs.enumerate() {
      for (hid-idx, end) in hidden.enumerate() {
        line("i" + str(in-idx + 1), "h" + str(hid-idx + 1), ..arrow-style)
        // Slide i1 annotations toward the hidden layer and i2 annotations toward the inputs.
        decorate-ih(
          edge-point(start, end, if in-idx == 0 { 1.5 } else { -1 }),
          in-idx + 1,
          hid-idx + 1,
        )
      }
    }
    for (idx, start) in hidden.enumerate() {
      line("h" + str(idx + 1), "o", ..arrow-style)
      decorate-ho(edge-point(start, output, 0), idx + 1)
    }
  }

  draw-network(
    0,
    [*regular NN*: one value per weight],
    (pos, in-idx, hid-idx) => weight-label(pos, 0.35 * in-idx - hid-idx * 0.15),
    (pos, idx) => weight-label(pos, 0.35 * idx - 0.15),
  )
  draw-network(
    3 * layer-gap,
    [*Bayesian NN*: distribution per weight],
    (pos, in-idx, hid-idx) => gaussian(pos, in-idx - hid-idx),
    (pos, idx) => gaussian(pos, idx - 1),
  )
})